On this page
Who here has time to do a full-blown content audit every month? Or every six months, for ten agency clients? Or whenever someone decides it’s time for another blog audit, even though you did one last month and nothing from it was implemented?
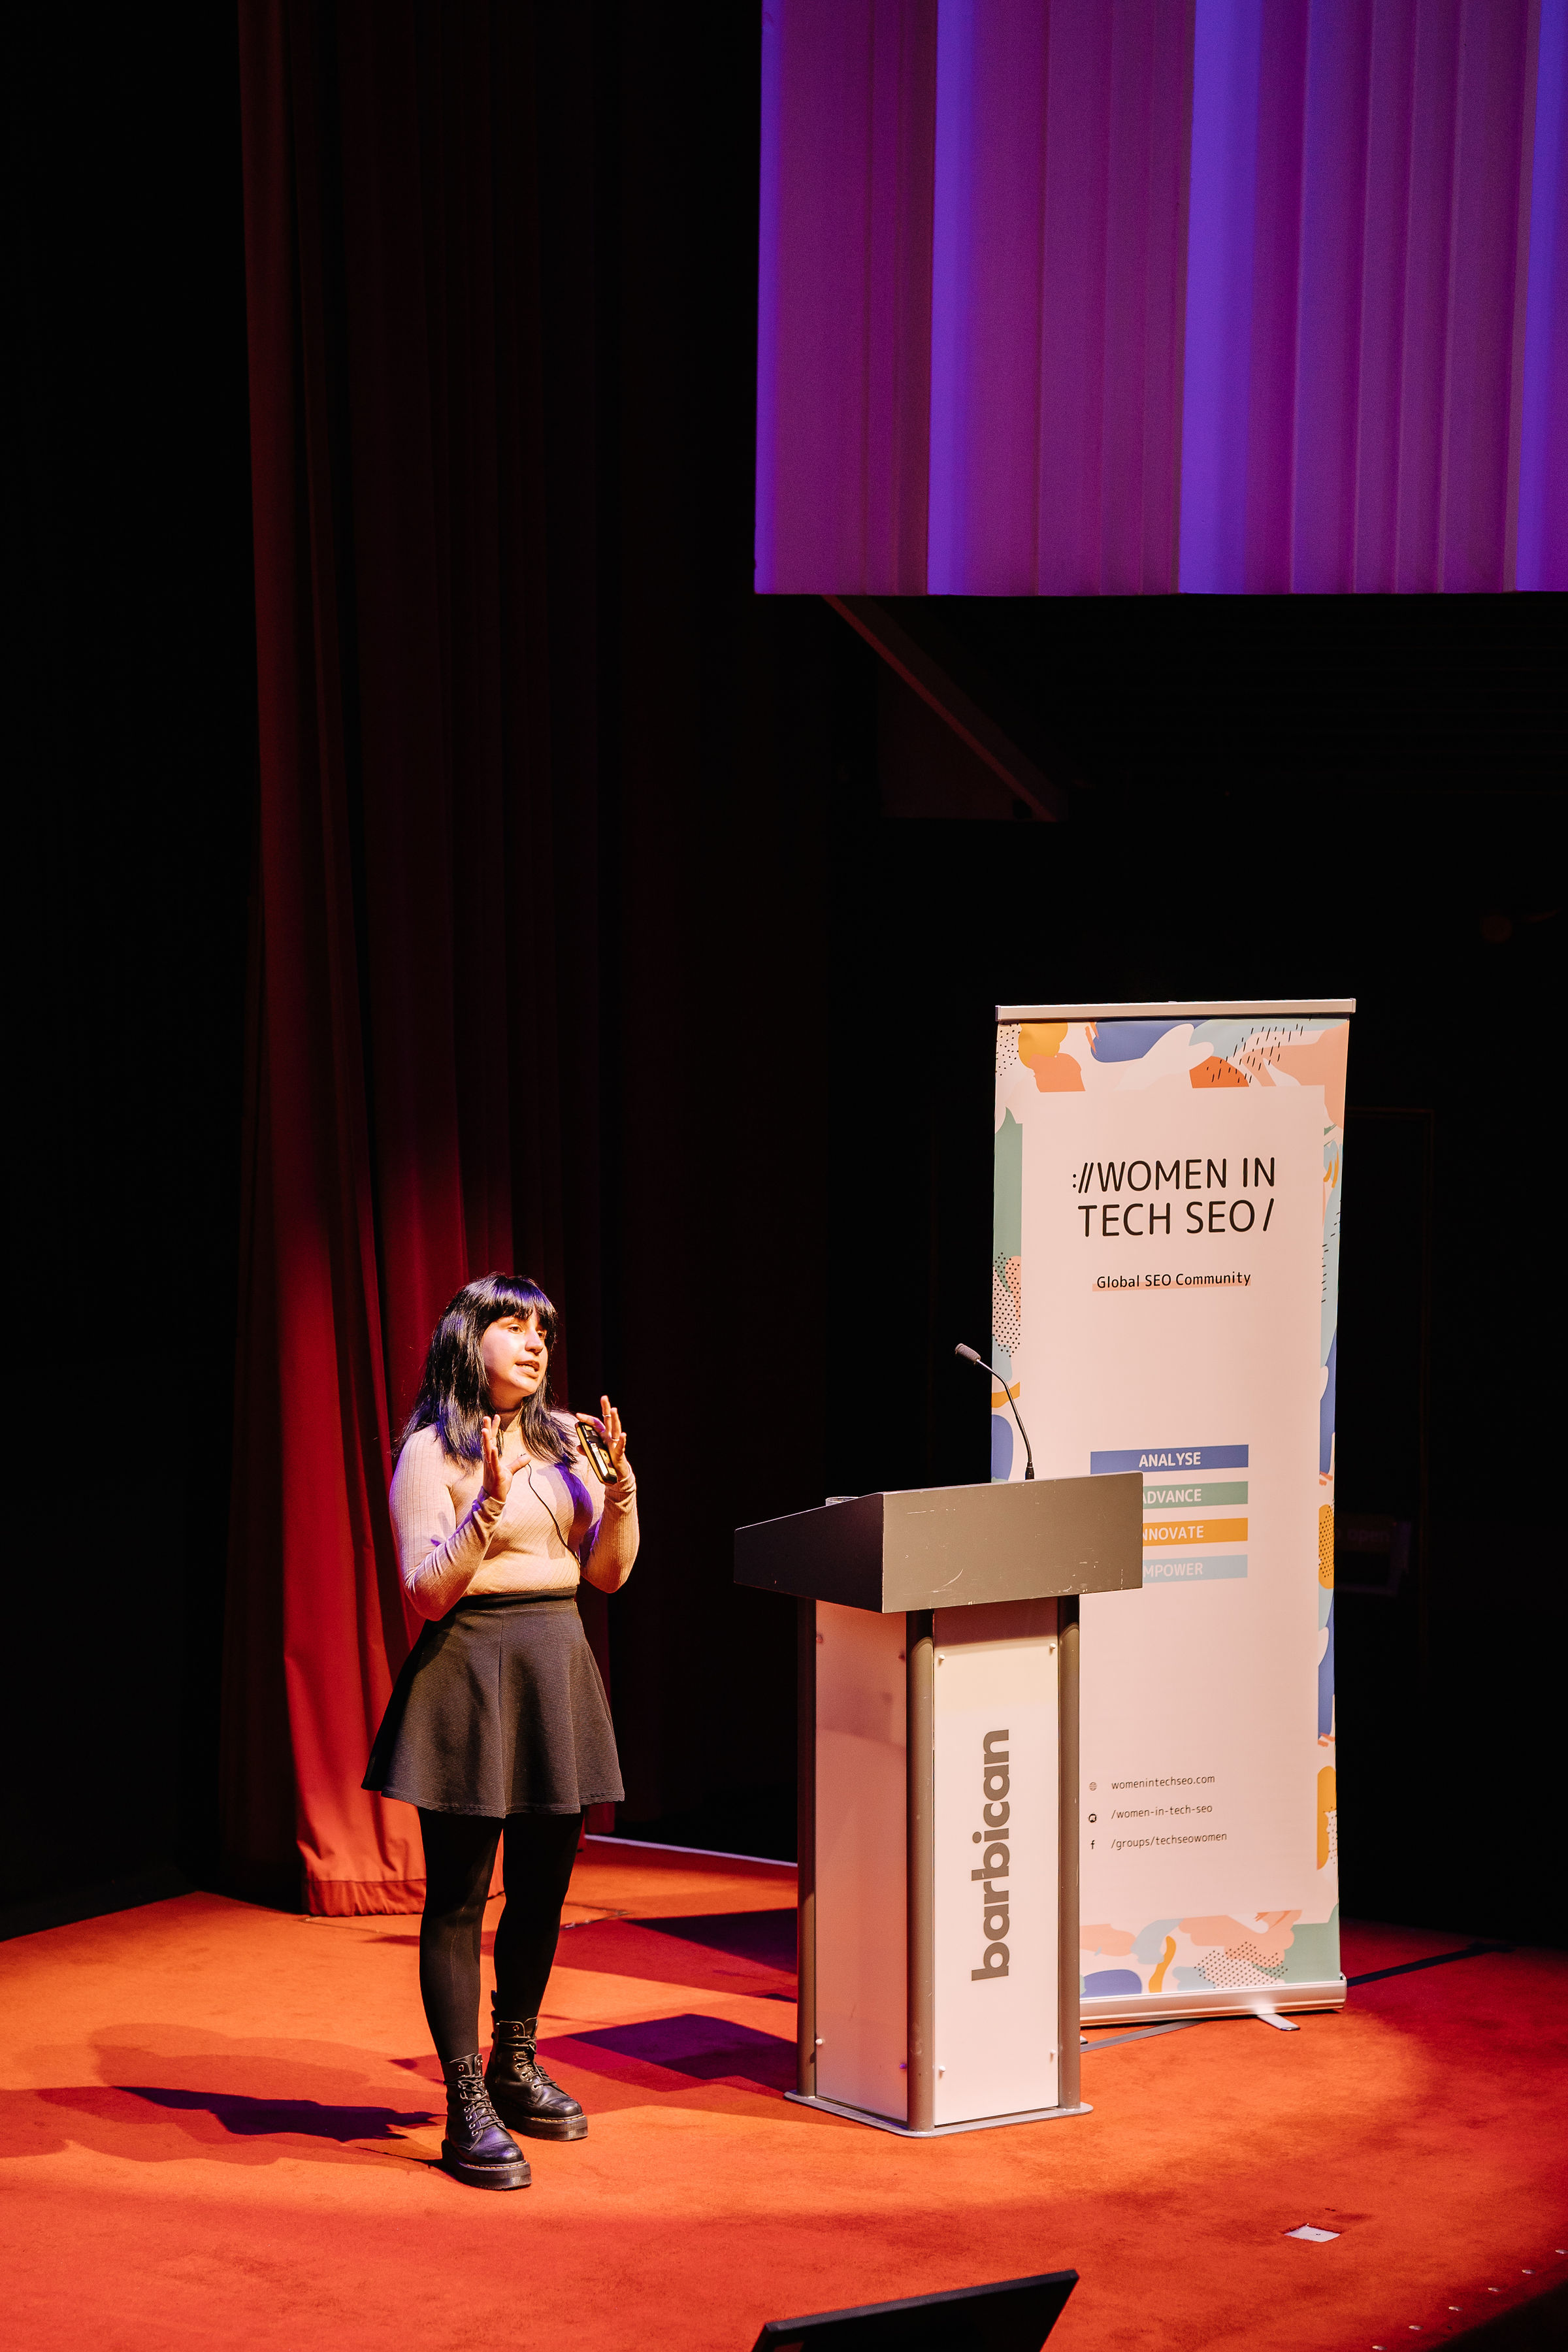
That’s how I opened my talk on the BrightonSEO main stage in October 2024: 120 slides, 20 minutes, a full room, and a question I already knew the answer to. Nobody has that time. I certainly didn’t, back when I was doing these audits by hand, and I hated it. This write-up is the full version of that talk, with the tools updated to where they stand in October 2026.
About this talk
- Event: BrightonSEO, main stage
- City: Brighton, UK
- Date: October 2024
- Video: Watch the recording on YouTube
- Slides: Download the deck (PDF)
The clickbait in the title (and what this is really about)
Let me get the confession out of the way, as I did on stage. We are not going to fully automate the content audit. There is no one-click system at the end of this that spits out a finished blog audit. I wish I could give you that. I can’t, and anyone who says they can is selling something.
What we can do is take the same steps every content audit already follows and build a better system around them, one that serves you for years rather than for one client deliverable:
- Build better systems: a reusable audit database and template, not a one-off spreadsheet.
- Implement machine learning APIs wherever they give a better insight than a human with a filter.
- Automate the repetitive parts of the process.
- Ultimately, create a better audit, quicker.
The steps themselves are the ones you know. You organise your database (crawl, content, metrics). You understand the data by categorising your inventory. You evaluate performance and assign action items, which typically don’t get done, but you assign them anyway. Then you organise your deliverable into a prioritised list of recommendations.

What’s changed since I gave this talk
The framework has held up well. The tooling underneath it has moved a lot. The short version, with details in each section below:
- AutoML for text is gone. Google stopped training new AutoML text classification, entity extraction and sentiment models on Vertex AI in September 2024, and existing models stopped working in June 2025. Custom classifiers now mean Gemini prompting or tuning, which (Google’s own words) doesn’t support confidence scores.
- The Natural Language API has a v2. Its entity analysis no longer returns salience or Wikipedia URLs, and the v2 classification taxonomy has 1,091 categories, not the “1,300+” I quoted on stage.
- Screaming Frog now does embeddings. Version 22 (June 2025) flags semantically similar and low-relevance pages using LLM embeddings, which covers part of what I built by hand in 2024.
- Zero-click got bigger. With AI Overviews and AI Mode, “pages that get impressions but no clicks” is no longer an edge case, so it belongs in your custom metrics by default.
- Google’s helpfulness signals moved into core ranking (March 2024), and the leaked Content Warehouse documentation gave us a much better idea of how topical focus might be measured.
Stage 1: Organise your database
The goals at this stage are simple: accuracy, consistency and thoroughness in the way you collect your data and bring it together, whatever platform you choose. Nothing clever yet. Get this wrong and every model you run later is a beautifully automated way of being wrong at scale.
Crawling and scraping content
Why reinvent the wheel? For a normal site, Screaming Frog can crawl the site and scrape the full content of every page (or just the bits you want). Pair it with Google Analytics and Search Console, pop it into Google Sheets, and you’re done. If you’ve never set up custom extraction, I wrote a three-step scraping guide on MLforSEO.
Sites with more than 500,000 pages need a bit more. Screaming Frog has to be set up differently (connected to a database, not running on your laptop), you’ll likely need a scraping API, and if you’re dealing with a multi-million-page website, I still recommend Jess Peck’s BrightonSEO talk from April 2022 on how to build your own crawler. The process is similar, just with heavier plumbing.
Map the performance metrics that matter
From Google Analytics, you want user engagement data (are people engaging with this page or not?) and traffic data split by channel. From Search Console, you want search traffic data across web, Discover and News, whichever applies to your content.

One update for 2026: if you’re still reading bounce rate the Universal Analytics way, stop. In GA4, bounce rate is simply the percentage of sessions that were not engaged, and an engaged session is one that lasts longer than 10 seconds, has a key event, or has two or more page views. It’s a perfectly usable metric, it just doesn’t mean what it meant in 2019.
Then go a step further. Pull internal links (incoming and outgoing), backlinks and referring domains, and readability data such as Flesch Reading Ease, word count and average sentence length. Screaming Frog gives you most of this. Is this page valuable? Is it internally linked? Is anyone else linking to it? Is it written for the audience it’s meant to serve?
Build your own custom metrics
Then go further still. Don’t rely only on the metrics everyone else uses, especially if you work at an agency and need to justify what makes your audit different. In the talk, I gave a shout-out to Marco, whose work on content decay inspired a big part of this list.

- Branded vs non-branded share of the queries each page ranks for.
- Content decay score: how far a page has fallen from its own peak, not just whether traffic is down this month.
- Content type: seasonal, evergreen, interview, news. A seasonal page dropping in February isn’t decaying, it’s February.
- Share of clicks each article brings to the site, so you know what you can’t afford to break.
- Zero-click pages: pages that collect impressions but no clicks.
That last one has aged into the most important metric on the list. Since I gave this talk, AI Overviews rolled out widely and AI Mode followed. Pew Research Center found that Google users clicked a traditional result on 8% of visits when an AI summary appeared, against 15% when it didn’t (based on the browsing data of 900 US adults in March 2025). If a page’s impressions are steady and its clicks are sliding, that isn’t necessarily a content problem anymore, and your audit should be able to tell the difference before it recommends a rewrite.
Put the data together
How you combine it is a matter of preference. Most people will use Google Sheets; BigQuery is for the pros or for very big sites. What I rarely see, and wish I saw more, is people building the audit spreadsheet so that it can be visualised in Data Studio. Do that once and you have a template you can reuse a month from now, when your client asks for another blog content audit and you can show, with a straight face, that nothing has changed because nothing was implemented. To get there, you need to learn a little about joins (left, inner, full outer). If you need a starting point, the Content Performance Report template on Data Studio for Marketers is a good one to pull apart.
Stage 2: Understand the data (categorise your inventory)
Here’s where the fun starts. The goals at this stage: label as much as possible of what Google cares about (and what we, as people who make the web better, should care about), see what works, and see where the content fails.
Site structure and authorship
Start with the basics. Tag each page with its theme or page template, its site section and subsection, its author, its publish date, its last updated date, and how often it should be updated. Most of this can come from the URL, and the rest from Screaming Frog custom extraction.
For sites with no sensible URL structure and nothing useful in the title, I suggested AutoML Vision in 2024: upload screenshots of your templates and train a model to detect the page elements you then scrape. Since I gave this talk, that route has closed for most people, as Google has pushed AutoML users towards Gemini. Honestly, the simpler fix now is a multimodal model looking at a screenshot (or the rendered HTML) and returning the template type, and Screaming Frog can send page content to OpenAI, Gemini, Anthropic or a local Ollama model during the crawl. Treat it like any other classifier: check a sample by hand before you trust it.
Target intent and update needs
For target intent, personas and content freshness, I recommend a rule-based classification approach first. You can build rudimentary intent categories from titles (if it contains “how to”, it’s informational, and so on). It’s crude, but it’s transparent, and you can explain every label to a client.
Even better: classify the queries each page ranks for in Search Console, then assign the page’s intent based on them. This is where you find the interesting stuff. Maybe 90% of the queries a page ranks for are informational, but the page is a thin landing page. That’s a recommendation right there: turn it into an article and make the landing page more bottom-of-funnel. Customise the labels for every site and industry you work with; a fixed taxonomy will never fit everyone.
The pro move is to train a classifier on your niche’s content and queries. In the talk, I used an example from Mark Williams-Cook, who had around 100 million rows of query data and asked how he’d build a classifier on it. In 2024, my answer was AutoML Natural Language or Vertex AI.
Since I gave this talk, that answer has changed. Google stopped training new AutoML text models on 15 September 2024, and existing AutoML text models could only be used until 15 June 2025. The official migration path is Gemini prompting and tuning, and Google’s own comparison table is refreshingly honest about the catch: AutoML text supported confidence scores, Gemini doesn’t. Keep that in mind for the classification section below, because it’s the whole point.
For most teams in 2026, I’d pick one of three routes, and all three are written up on MLforSEO: a rule-based notebook that uses SERP features, a semantic approach with Google Cloud NLP and spaCy, or a zero-shot transformer approach with BART. If you want the reasoning behind each before picking one, start with search intent classification approaches explained.
A few more signals to fold into intent, whichever route you take:
- SERP features: if most of the features on a page’s SERPs are informational, the page is most likely ranking as informational too.
- User knowledge level: if the title says “beginner’s guide”, you know who it’s for. Tag it.
- The action you want the user to take: sign up to a newsletter, buy a product, book a call. The job to be done, and the implicit intent behind it.
Content topics and subtopics
How many of you actually do anything to understand what the content is about when you audit a blog? The easiest way is to use two of the most beginner-friendly machine learning tasks there are: classification and clustering.
- Classification sorts your dataset (here, all the content on the site) into predetermined categories.
- Clustering partitions your content into groups when it doesn’t fit any predetermined list, or when you need labels specific to your niche: blockchain, cybersecurity, medical, whatever it is.
For classification, I use Google’s Natural Language API. The process takes less than 20 minutes. I promise: I’ve tested it with complete beginners. You enter your URLs and content in a Google Sheet, run the script with a formula, and get a primary category (think news), a secondary category (politics, entertainment) and a tertiary one, each with a confidence score. The full walkthrough is my text classification tutorial on MLforSEO, and there’s a plug-and-play dashboard template for the output. I’m not going to duplicate the code here.
A correction since the talk: on stage I said the API classifies into 1,300+ categories. According to Google’s release notes, the v2 content categories taxonomy that became generally available in January 2023 has 1,091 categories across 11 languages. Still plenty for a first pass at a site’s topics.

Why use a dedicated API rather than a chatbot? Because the categories are predictable, which matters when you present the data to clients, and because you get a confidence score. That score lets you, the consultant with a fully functioning, thinking brain, say: the model is 60% confident here, my threshold is 85%, so I won’t use that label or present it to my client.
On stage, I begged the audience not to ask ChatGPT for that number, because it will just generate one. It sounds like confidence. It means nothing. Two years on, I can back that up with more than a raised eyebrow. A study presented at ICLR 2024, Can LLMs Express Their Uncertainty? by Xiong et al., found that LLMs tend to be overconfident when asked to verbalise their confidence. And as above, Google’s own documentation says Gemini doesn’t support confidence scores the way AutoML did. Generative models are great at being creative, not at being precise. Use them where that’s fine; use a purpose-built classifier where you need a number you can set a threshold on.
For subtopics, move to clustering. LDA (latent Dirichlet allocation) takes a collection of documents and works out both the main topics across the site and the mix of topics within each document. It gives you every document that mentions a topic, every topic within a document, and the keywords that define each topic. (Another small correction: on stage I said LDA dates from the 2010s. Blei, Ng and Jordan published it in 2003, which makes it older than most of the tools in your stack.) My LDA topic modelling guide and the no-code output organiser template cover the how-to.
BERTopic, created by Maarten Grootendorst, is the more modern alternative. Its strength is that it’s modular: for every step of topic modelling (embeddings, dimensionality reduction, clustering, tokenising, weighting and, optionally, representation tuning), you can pick the model that suits your data. It sounds advanced, but if you’ve ever built clusters with LDA and wished you could change one part of the process, you’ll see the value immediately.

Since I gave this talk, the representation step is where BERTopic has become most useful for audits. It can now hand each cluster to an LLM (via OpenAI, Ollama, LiteLLM, LangChain, Cohere and others) to write a readable topic label from the keywords and representative documents. That’s a good use of a generative model: the clustering is done by a deterministic pipeline, and the LLM only names the result. Grab the BERTopic notebook or read the BERTopic guide for the walkthrough. In both cases, feed the topics back into your audit spreadsheet.
Identify and map entities to topics
Why do entities as well? Because topics tell you an article is about news, politics. Entities tell you what exactly it mentions: which people, places, organisations and concepts, in what sentiment, in what wording, and how prominently across your whole content collection.
Same API, same process, no more than 20 minutes: pop your content into the Google Sheet, run the script from the menu and get entity data in seconds. The step-by-step is in my entity extraction tutorial, with a no-code template and a Python version if you outgrow Sheets.
Since I gave this talk, the API has gained a v2 with a PaLM-based entity model, and two fields I relied on are gone from it: v2 entity analysis no longer returns salience or Wikipedia URLs. If prominence matters for your audit (it usually does), either keep calling the v1 endpoint, which still returns salience, or approximate prominence from mention counts and positions in v2. Know which version your script calls before you compare this year’s audit with last year’s.
Then map entities to your topics, classification labels and intent categories, so you can see which entities are discussed in each topic. Now imagine comparing that with how your competitors write about the same topics. That’s a far more useful content audit than counting words. If you’re choosing between entity APIs, I compared them in NLP APIs for entity and sentiment analysis vs generative AI.
Evaluate helpfulness and E-E-A-T
Aleyda Solis built a checklist from the questions in Google’s own guidance on creating helpful, reliable, people-first content. With a bit of creativity, you can automate more of those checks than you’d think, because by this point you already have most of the data:
| Google’s question | What you can check it with |
|---|---|
| Are you producing lots of content on many different topics in hopes that some of it might perform well? | Number of content pieces, your topic models, number of topics |
| Does your content leave readers feeling they need to search again? | Engagement rate (or bounce rate), engagement time |
| Is it self-evident who authored your content? Do pages carry a byline? | Author byline, scraped with Screaming Frog |
| Do bylines lead to further information about the author? | Author pages: do they exist and are they linked? |

I colour-coded the full list: green for questions you can check easily, yellow for ones that need a custom model or calculation, red for the few that are genuinely hard at scale. Most of it is green or yellow. Building Google’s own guidelines into the way you audit content will make the outcome better, full stop.
Two things have happened since. First, Google confirmed with the March 2024 core update that its helpful content system is now a core part of its ranking systems, so there’s no separate “helpful content update” to wait for. Second, the guidance now asks about automation directly: is the use of automation, including AI generation, self-evident to visitors, and are you explaining how it was used? Add those to your checklist. They’re easy greens: does the page have a disclosure or not?
The bigger one for me is topical focus. My “how many topics is this site writing about?” check came from Google’s question above. Then, in May 2024, a few months before the talk, the leaked Content Warehouse API documentation surfaced attributes called siteFocusScore and siteRadius. As Mike King put it in his analysis for iPullRank, Google appears to be vectorising pages and sites and comparing page embeddings to the site embedding to see how off-topic a page is. We don’t know how those attributes are weighted, so don’t treat them as ranking factors. But the idea that topical drift is measurable is now well supported, and you can measure it yourself.
You don’t even have to build it. Screaming Frog 22, released in June 2025, uses LLM embeddings to populate “Semantically Similar” and “Low Relevance Content” filters in the crawl: the first catches pages covering the same subject in different words (hello, cannibalisation), the second flags pages that sit far from the site’s overall theme. That’s the 2026 version of the topic-count check, and it plugs straight into stage 1.
Audit semantics
Semantics, for an audit, comes down to three shifts:
- From disorganised to organised: do you refer to things the same way every time? Have you tagged, categorised and presented your topics thoroughly and consistently?
- From copying to adding: instead of the same ten tips everyone else wrote (or that ChatGPT wrote, everywhere), do you add something new? Is the uniqueness in the information, the depth, or the presentation? On MLforSEO, I’ve covered how information gain is thought to work.
- From keywords to user experience: what are people searching for first, what do they search for next, what platforms are they on, and which related topics and entities sit around the query?
Then turn those into custom metrics: keyword and entity density, topical relevance, and query-content match. For query-content match, I used KeyBERT (also by Maarten Grootendorst), which extracts the most important term from a piece of text, so you can compare the main term of a page’s title with the main term of its content, and check both against what you want to rank for. You can run it from a Colab template or follow the KeyBERT tutorial.
What I’d add today: embeddings-based similarity between each page and the queries it ranks for, at the level of the passage, not just the page. AI search systems retrieve and cite chunks, not whole URLs, so a page can be a perfect topical match and still bury the answer in paragraph eleven. I wrote about this on MLforSEO in the chunk, not the page. Google’s current text embedding model, gemini-embedding-2 (generally available since April 2026), or the embeddings Screaming Frog already collects, will do the job.
Stage 3: Evaluate performance and assign action items
Two more steps. The goals here: a simple, adaptable system, because you’ll reuse it for the same client and for clients in other industries; consistent evaluation criteria, so every site is judged against the same bar (that’s roughly how Google does it, if you don’t count Forbes); and a forward-looking approach: who’s next, and who will actually implement this?
If/else logic is your best friend at this stage. Build a checklist of best practices for every component you assessed: readability, titles, meta descriptions, intent match and so on. Mine is around 500 rows long, and each row says, in effect, if the value falls in this range, that’s not good. When I run a blog content audit, everything lights up green, yellow or red immediately.

- Translate each checklist item into a conditional statement. If the title is too short: what needs fixing, and where do you go to learn how to fix it?
- Translate the statements into code for your platform: Apps Script for Google Sheets, Python if you’re working in BigQuery.
- Give every assessment an action item and an owner, a person or department responsible for implementing it.
- Not comfortable coding? A Data Studio dashboard can hold the same logic in calculated fields, and it saves a lot of time on future audits.
- Automate the alerts. Zapier (or n8n, or a scheduled Apps Script) can notify you when a page drops below a threshold, so you don’t wait for the next audit to find out.
Where do LLMs fit here in 2026? Mostly in the wording, not the decision. Gemini in Google Sheets now has an AI function that can draft a plain-English explanation of why a row failed, on the Workspace plans that include it. Useful. But keep the decision itself (does this page pass or fail?) in rules you can explain and repeat. I go into why in rule-based vs AI-powered automation.
Stage 4: Organise your deliverable
Then, finally, you build the prioritised list of recommendations. Yay. To me, a good audit deliverable is:
- immediately actionable
- extensive and thorough
- insightful
- contextualised and relevant for multiple stakeholder groups
- built to promote action
- something that evokes immediate FOMO
I’m a geek, and that’s what I want to see. But you’re not auditing for me. You’re probably auditing for someone extremely busy who does not want to read an 80-page document. So ask your client what a good deliverable looks like for them.
If you do have to write audits for someone like me, and consistently (say you’re an agency justifying why the audit costs what it costs), build a template. Each audit section explains why it matters, gives context on the metrics and checks, and links a downloadable list with all the relevant data, actions and owners. The only part that changes per client is the pattern unique to that analysis. Content patterns are a concept I borrowed from programmatic SEO, and they work beautifully here.

Connect Google Docs to Google Sheets with Apps Script, and the deliverable fills itself from your audit data, instead of being written from scratch every time. Zapier can do the same integration if you’d rather not touch code.
Reduce, reuse, recycle: make it 1% better every time
My final note on stage, even though I was already over time: how often do you do these audits? Every time you run one, you can make the system a little better. Reduce some of the complexity. Reuse the components that worked. Recycle the rest. A process that gets 1% better each time compounds; one that stays the same quietly gets worse.
I don’t expect you to build all of this before your next audit. Take one concept, say the intent classification from Search Console queries or the if/else checklist, and add it. Then add another next time. And when you’re ready, the same system extends to rank analysis, SERP analysis, competitor content audits and gap analysis, cross-platform opportunity analysis, and first-party user feedback for content revisions.
Where to go next
Twenty minutes for a talk on machine learning is always a challenge, and on stage we only scratched the surface. Everything above is written up step by step in the content audit guides on MLforSEO, alongside a separate guide to internal link audits with ML, which grew out of an earlier BrightonSEO talk of mine.
If you’d rather learn the classification, clustering and entity work with structure, practice files and feedback, my Introduction to Machine Learning for SEO course in the MLforSEO Academy covers exactly these models, built for SEOs who don’t code (yet). And if the reporting side is the bottleneck, Data Studio for Marketers has templates to build your audit dashboard on.
The full deck is here as a PDF. Want me to give this talk at your event? Book me to speak.
Frequently asked questions
Can you fully automate a content audit with machine learning?
No, and I’d be suspicious of anyone who says otherwise. You can automate data collection, labelling (intent, topics, entities), the pass/fail checks and even the first draft of the deliverable. The judgement calls, like which recommendation matters most for this business right now, still need a person.
Why use the Google Natural Language API instead of ChatGPT or Gemini to classify content?
Because it returns predictable categories and a confidence score you can set a threshold on. Generative models will happily give you a confidence number if you ask, but research presented at ICLR 2024 found LLMs tend to be overconfident when they verbalise confidence, and Google’s own documentation says Gemini doesn’t support confidence scores. Use generative models for labelling clusters or drafting explanations, not for decisions you need to defend.
What replaced AutoML for custom text classification?
Google stopped training new AutoML text models in September 2024 and retired existing ones in June 2025, recommending Gemini prompting and tuning instead. For most SEO teams, a rule-based classifier, a zero-shot transformer model or a small supervised model trained on your own labelled queries is simpler, cheaper and easier to explain.
How often should you run a content audit?
As often as someone will act on it. A reusable system changes the maths: once the database, labels and checks are built, a re-run takes hours rather than weeks, so you can audit quarterly and set automated alerts for the pages that matter most in between.
Do I need to code to do any of this?
Not to start. Text classification and entity extraction run from a Google Sheet with a formula, Screaming Frog handles scraping and embeddings, and Data Studio can hold your if/else logic in calculated fields. Python and Colab help once you need topic modelling at scale or BigQuery.
Written by Lazarina Stoy
Organic growth and AI automation consultant, speaker, and founder of MLforSEO and Data Studio for Marketers. I help marketing teams use AI and automation in ways that are practical, sustainable and scalable.