On this page
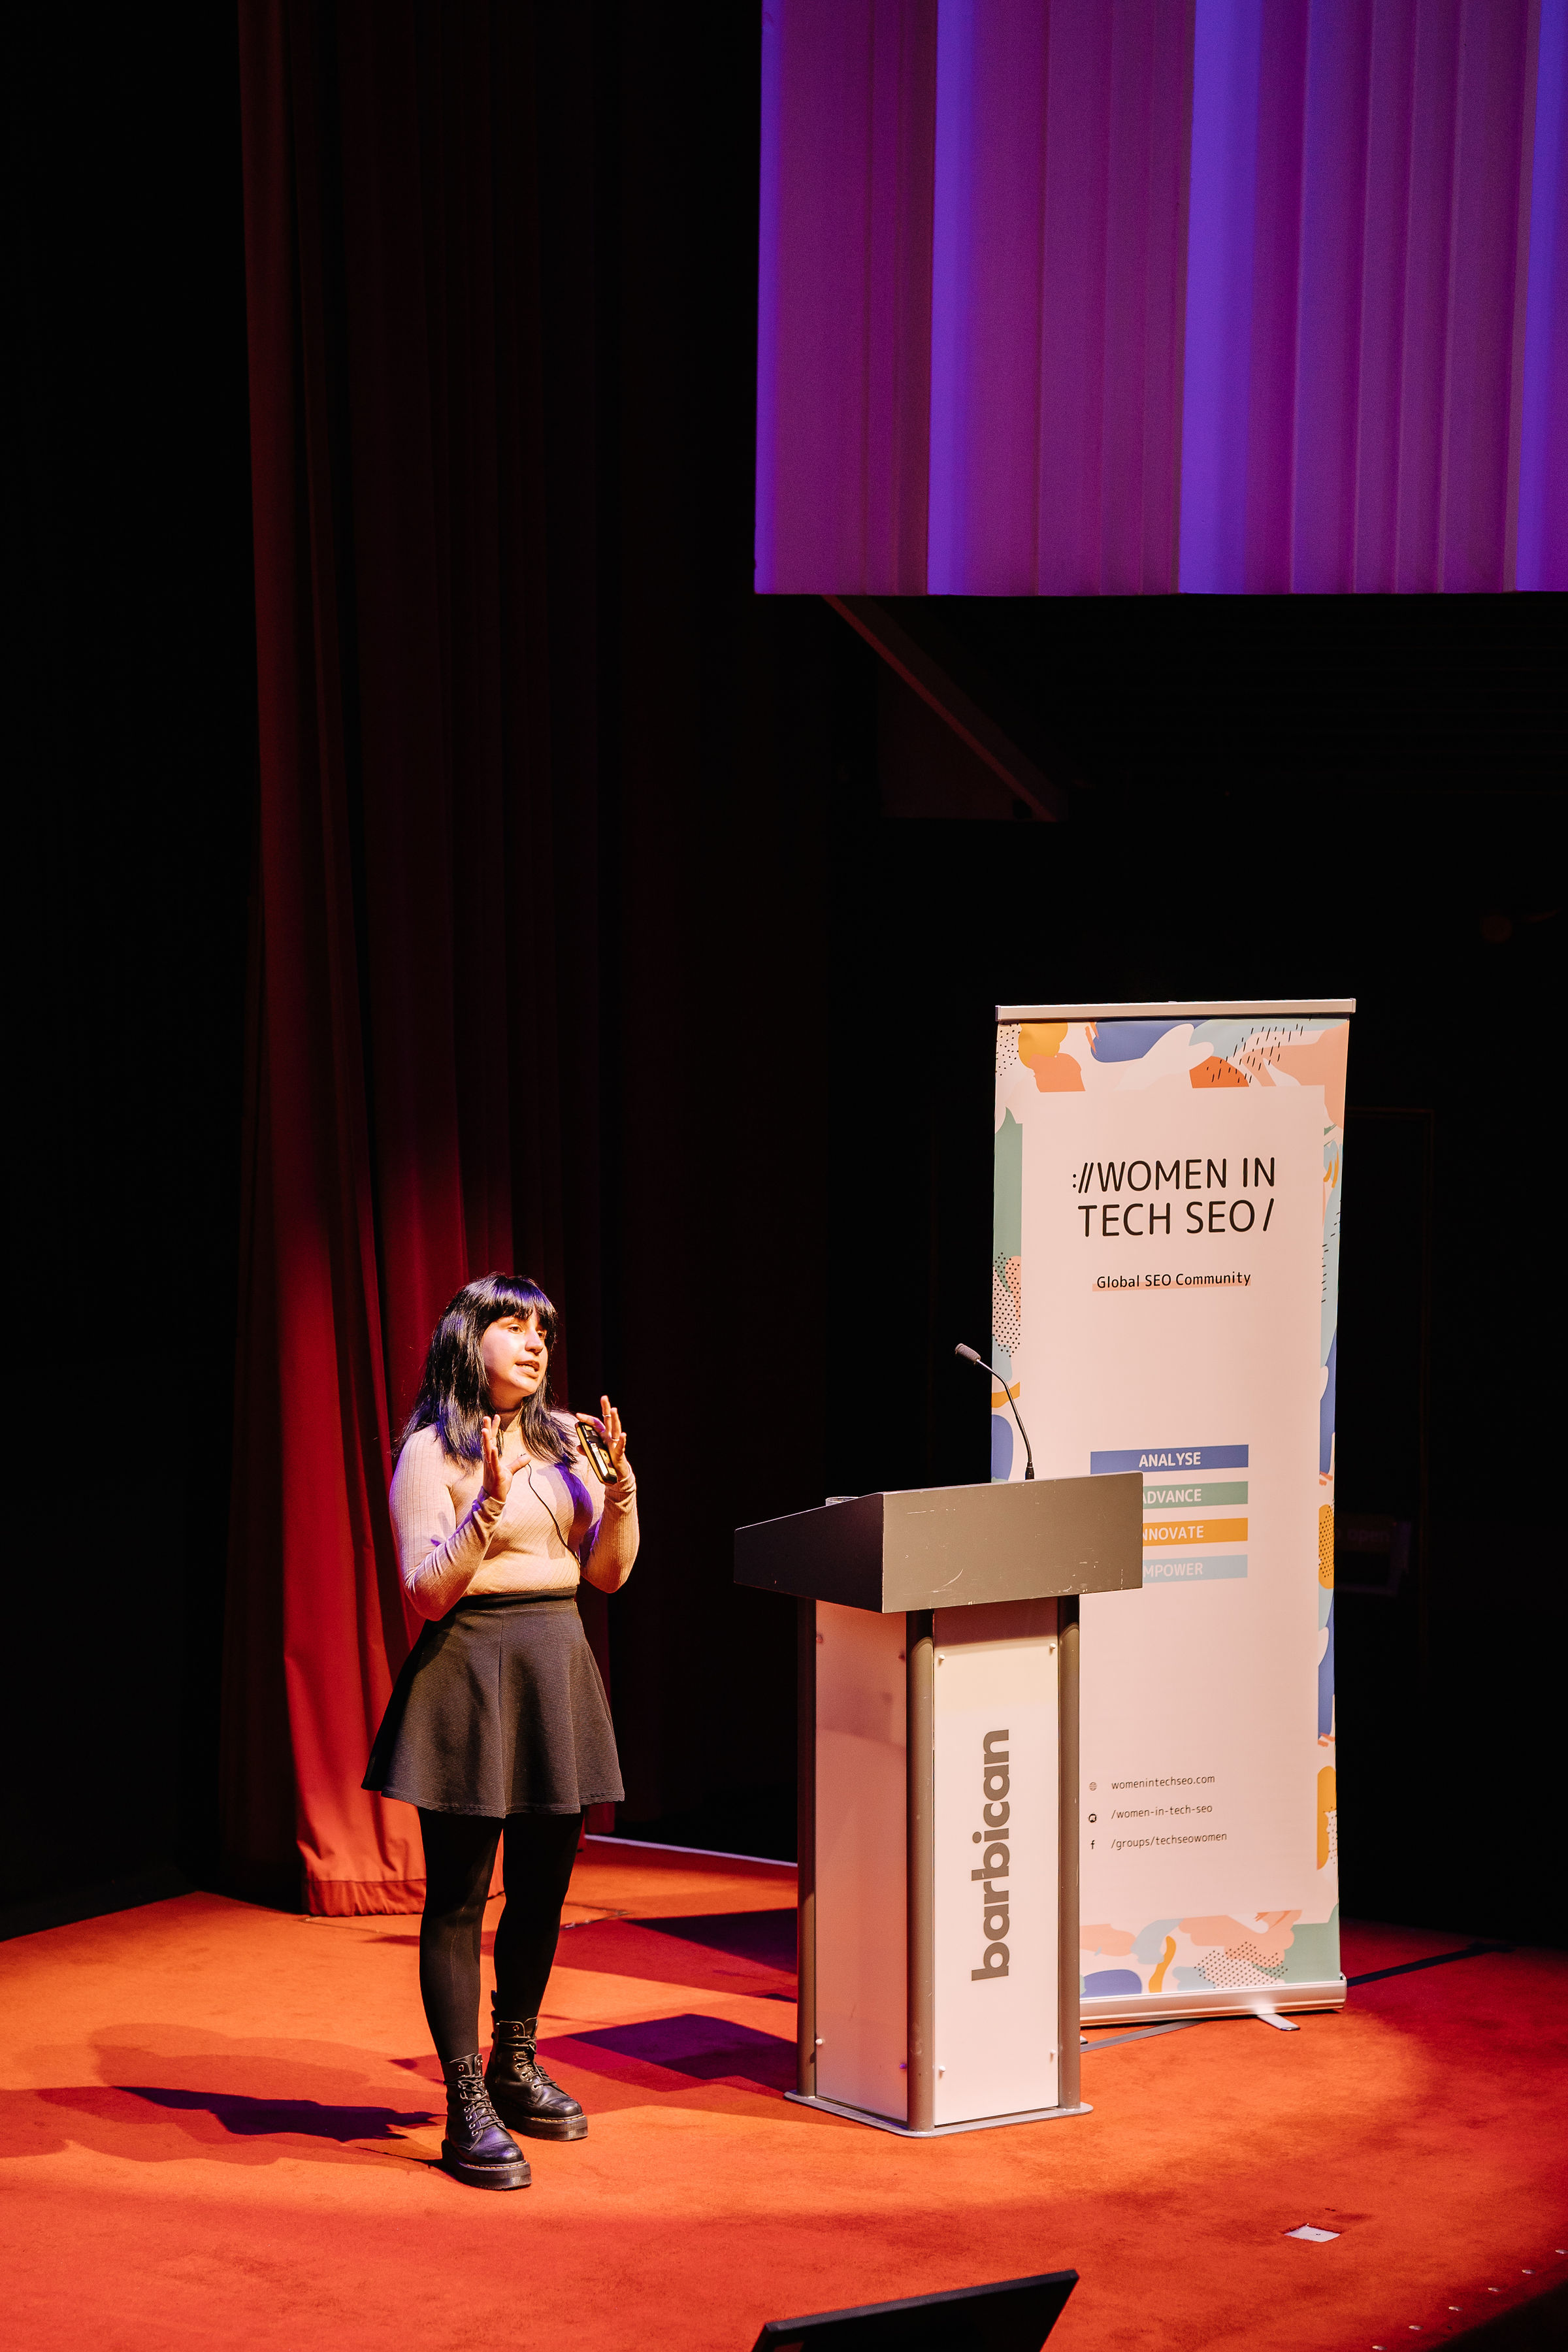
In October 2022 I walked onto the BrightonSEO stage and told a room full of SEOs that the best keyword research tool they had was the one Google rebuilds for them every day: the search results page itself. This is the write-up of that talk, with the methods updated to where they stand in 2026.
About this talk
- Talk: How to Incorporate Machine Learning in Your SERP Analysis
- Event: BrightonSEO
- City: Brighton, UK
- Date: October 2022
- Slides: download the deck (PDF)
I opened that session with a confession I’d make again today: I’m not a developer. I was at Intrepid Digital at the time (they’d never have forgiven me if I hadn’t mentioned it), and most of what I built for the talk ran in Google Sheets and Apps Script, at the click of a button. That was the point. I wasn’t there to show off a system nobody else could run. I wanted people to leave thinking “I could do that on Monday.”
Four years on, the argument has aged better than the tooling. GPT-3 has come and gone, Google’s Natural Language API has a second version, and the SERP now opens with an AI Overview for a lot of the queries I care about. So in this write-up I’ll walk you through the talk as I gave it, and tell you, section by section, what I’d do differently now.
Here’s what I’ll cover:
- Why the SERP is research you’re not using, and why I flipped the usual content process around.
- How I structured the analysis with the MoSCoW framework, so nobody drowns in nice-to-haves.
- The five analyses from the talk: competitors, entities, sentiment, search intent and language use.
- The one I deliberately left out (rank analysis), and why that decision looks even better in the age of AI search.
- What I’d change if I gave this talk tomorrow.
Google has already done the research. Why aren’t we using it?
I started with three numbers. In 2022, Google said it ran around 800,000 experiments a year and shipped thousands of improvements to Search, and Google handled the vast majority of all searches. The 2026 versions of those numbers tell the same story: in 2023 Google ran more than 700,000 experiments that resulted in more than 4,000 improvements to Search, and it still handles around 90% of worldwide search traffic, according to StatCounter. Despite what you might hear about TikTok, ChatGPT or whatever is “the new Google” this quarter, that page still deserves our attention.
Then I walked through the anatomy of a SERP, with a shout-out to Mordy Oberstein, whose “Anatomy of the SERP” guide and examples I leaned on. Every element on that page has a job. Google promotes (ads and partners), helps you find (maps, local packs), understand (organic results, knowledge panels), discover (related topics), do (recipes, how-tos, ratings), buy (shopping without leaving the page), choose, broaden, refine and specify (filters and refinements), highlight (creators, videos, featured snippets) and enrich (People Also Ask, image packs). In 2026 I’d add one more job to that list: answer. AI Overviews and AI Mode summarise the result set before anyone scrolls.
My point was simple. Google tests results-to-intent alignment continuously and rigorously, using data none of us will ever have, and it publishes the outcome of that research on the SERP, for free, every time someone searches. So why not tap into it?
Instead, the classic content process goes like this: you get an idea, you write about it without much thought about the output, you publish and hope for the best, and two months later nothing has happened. The client asks why the piece isn’t ranking, someone suggests a rewrite, and around we go. I proposed putting the user, and the data, first:

- Idea: start from your keyword research and content strategy.
- Study the SERP: it’s probably your best indicator of what users want for this topic.
- Assess: who ranks, how they perform, and what they have in common.
- Optimise: structure your article’s bones around what you’ve learned.
- Write: with the user, the search data, your competitor data and your brand’s own angle in mind.
The last step matters more than people think. If you have well-defined brand voice guidelines, this is where you work out what you, specifically, can add to a topic, using the structure the data gives you. The data tells you the bones. You bring the personality.
How I structured it: must have, should have, could have
Here’s the thing about machine learning talks: they make everything look essential. So I sorted every recommendation into the MoSCoW framework, borrowed from project management.

- Must haves: no more than about 60% of your effort. The basics that pay off every time.
- Should haves: the next layer, still templated and repeatable.
- Could haves: around 20%. The fun, experimental stuff that isn’t strictly necessary. Whether you should do it is a separate question, and we’ll get to that.
- Won’t haves: things I either didn’t have the skills to build or didn’t think were worth it.
Every must-have and should-have came with a template people could copy straight after the session, so the groundwork was done and they could spend their energy on the more advanced bits.
Two sets of requirements sat underneath all of it. The analysis prerequisites: solid keyword research, a content strategy and brand voice guidelines. Without them, you’re analysing the wrong SERPs with no idea what to do with the answer. And the system requirements: I wanted something flexible, reusable and maintainable that my team could run without me. Not an end-to-end custom build. Not something scary. If you’re building for a different team, choose differently, but decide on purpose.
1. Competitor analysis: who are you actually competing with?
I started with something easy and fun. Your must-have questions: who are your search competitors, what’s their visibility, what’s their traffic potential, and which URLs keep reappearing across your keywords? I pulled this from DataForSEO’s SERP competitors data (I’m not affiliated, I promise), either through their Google Sheets add-on or straight from the API, and plotted a competitor positioning map: ranking against visibility against traffic potential, one bubble per domain.
The should-have is where it gets interesting. Tag every competitor by site type. Wikipedia and Investopedia are wikis. Coursera and Udemy are course platforms. Then there are news sites, review sites like G2 and TechTarget, and technology vendors. Then map each site type to a holistic intent: wikis, courses and news are informational, reviews are commercial, vendors are transactional or navigational.

Suddenly the positioning map tells you what kind of content you’re up against, not just whose. Some positions are effectively reserved for the big players in their niche, because Google still wants a diverse set of results, especially for ambiguous queries. Then calculate share of search per domain, per site category and per intent category. In my (very tech-heavy, which I admitted on stage was a bad choice for a general audience) dataset, wiki-style sites took around 30% of the share of search. That alone changes what you should write.

The could-have was the bit people photographed. I pulled bulk SERP data (result type, rank, domain, URL, title and meta description) for a much bigger keyword set, then asked GPT-3 to classify every domain into a site category and the intent of every title and description. I used a script Danny Richman had shared (thank you, Danny), which he’d had GPT-3 write for him. Classifying tens of thousands of domains took minutes. I also had a side note about scale: Google Sheets has a hard cell limit and makes you juggle 100 tasks at a time, while the same API from Python has no such ceiling.

Since I gave this talk: I’d still classify competitors, but I’d never send a model a bare domain name and hope again. Today I start with a free, rule-based lookup for the domains I already know, send the model a couple of ranking titles per domain (far easier to judge than a URL), and use structured outputs, so the model can only answer from my category list. That one change removes most of the clean-up I used to do by hand. I’d also calculate share of search two ways: share of ranking slots, and a click-weighted share where position 1 counts for far more than position 9. When I re-ran this in October 2026 for a set of machine-learning keywords, course platforms owned the biggest slice and forum threads from Reddit and Quora held an average position of 2.5. For those keywords, you’re competing with community discussion as much as with other publishers.
2. Entity analysis: what is everyone talking about?
Once you know who ranks, explore what they say. The must-have here is entity extraction on the titles and meta descriptions you collected, using Google’s Natural Language API. I made a point of this on stage: the code wasn’t new. Google had published it as a sample years earlier. If you aren’t experimenting with entity analysis, it isn’t because it’s hard. It really is an API key, a Sheets template and a button.

You get each recognised entity, its salience (how important it is to the text), the sentiment score and magnitude it’s mentioned with, and the number of mentions. Then you visualise: the most common entities across the whole SERP set, the URLs that mention the most entities, and, once you blend the entity data with your ranking data, how entities and their sentiment sit across positions 1 to 10. For the should-have, check which of those entities exist in Google’s Knowledge Graph. Daniel Heredia has a beginner-friendly Apps Script tutorial for the Knowledge Graph API that does exactly that.
The could-have was rank prediction from entity presence in titles and descriptions. I said it then and I’ll say it again: only if you have a very large dataset and a very large budget.
Since I gave this talk: Google released v2 of the Natural Language API in 2023 on a newer model, and it dropped the salience score, the Wikipedia URLs and the entity-sentiment method (release notes). For this kind of SERP analysis I still use v1. I also tried the free spaCy route on my 2026 sample data, and its small model tagged “machine learning” as a person. Which is a lovely illustration of why I keep recommending purpose-built, knowledge-graph-backed APIs for entity work. If you’d like the long version, I compared the options in which NLP API to use for entity and sentiment analysis on MLforSEO.
3. Sentiment analysis: who’s for you, and who’s against you?
I flagged this one as totally optional, but very handy for online reputation management or for brands with sensitive keyword sets. Same API, same kind of template: feed in your titles and descriptions, get a score and a magnitude back. Two examples from the talk. For “why is Jeff Bezos inspiring”, a ranking title calling him an inspiration to all came back slightly positive (I’d have called that glowing, but fine). For “how do you know if an Amazon seller is legit”, a title about not getting scammed came back slightly negative.

Plot sentiment against average rank, for titles and then for meta descriptions (more data, better picture), and patterns jump out fast. Then the useful bit: list every publication by the sentiment it leans towards, and you’ve found your allies and your loudest critics. For the should-have, filter to the entities that matter to you. When I filtered for Amazon in that dataset, the sentiment was mostly negative, which, as a consultant, is precisely the thing you’d want to counteract with content. The could-haves: analyse the full pages rather than snippets, and (crystal ball time) predict performance from the sentiment make-up of a SERP, for example when one controversial, high-magnitude result always holds a top-10 spot.
I also had a small rant on stage, and I stand by it: we SEOs are very bad at using technology that’s already sitting there. The same entity and sentiment scripts can find internal link opportunities, content opportunities and topics at scale, analyse first-party feedback, Q&A, YouTube comments, and support reputation management. My previous BrightonSEO talk, on internal linking audits, was built on exactly that idea.
Since I gave this talk: v2 of the API is a genuine upgrade for sentiment, and it still returns both score and magnitude. I now label results as positive, negative, neutral or mixed: a score near zero with a high magnitude isn’t neutral at all, it’s strong positive and negative statements cancelling out, which is often exactly the review or forum thread you want to read.
4. Search intent analysis: beyond the four buckets
The must-have was labelling intent at the level of each ranking title and description, with the same GPT-3 process as before. But instead of stopping at informational, commercial, transactional and navigational, I suggested richer schemes: funnel-based intent, desired-action intent and verb-based intent.

The should-have is turning those labels into understanding. Where are the gaps? Where are the opportunities? How do positions, domains and entities relate to intent? And where a handful of pages matter a lot, say, because they’re very negative about your brand, scrape them and read what they actually say. The could-have was building your own intent model, for those with the skills (and the patience).
Since I gave this talk: I’m more careful about one thing. Intent categories are useful, but they aren’t exclusive. Plenty of queries carry mixed intent, so I treat a label as the dominant intent, never the only one. I also wouldn’t reach for a general-purpose LLM first: I compare rule-based, classic ML and transformer approaches in search-intent classification with machine learning, and the honest answer is that it depends on your data and how much consistency you need.
5. Language use analysis: the n-grams Google rewards
Last of the five, and the one I’m fondest of, because it’s the clearest example of “if you can’t code, ask for help.” I asked GPT-3 in the OpenAI playground to write me an Apps Script custom function that finds the n-grams (groups of words) in a piece of text. It took a few tries to get the prompt right, but it worked, and I could run it over every ranking title and description.
Count the bigrams and trigrams, and you see which keyword combinations dominate the titles that rank. In my dataset, “what is” was miles ahead of everything else. That’s not a keyword insight. It’s a format insight: Google wanted definitions for that set of queries.
Since I gave this talk: that GPT-3 function split text into n-grams but never counted them, lowercased them or stripped punctuation, so I’ve replaced it with a tested =NGRAMS() custom function (it’s in the MLforSEO code hub). And I’d add one lesson: run it twice. “What is” is made entirely of stop words, so if you remove stop words first, as most tutorials tell you to, the most useful finding disappears. Keep stop words to see title patterns; remove them to see topics.
The won’t-have: rank analysis
You might have noticed something missing. I did it on purpose, and I said so on stage (with a very dramatic pair of eyes on the slide). Rank analysis gets its own MoSCoW: your current position and featured snippet appearance as must-haves, changes in rankings and SERP appearance over time as should-haves, and then the crystal-ball could-haves: predicting CTR gains from a position change, predicting how a SERP’s make-up shifts with seasonality or big yearly events, predicting where newly published content will land.

I flew through it because existing tools already did most of this well, and because “you could” doesn’t mean “you should”. In hindsight, I was right to be lukewarm, just not for the reason I gave. The bigger problem with rankings now is that they’re measuring the wrong thing for a growing share of searches. When an AI Overview answers first, your position tells you where your link sits in a list; it doesn’t tell you whether you were chosen as a source. Beatrice Gamba makes that case brilliantly in your rank tracker is lying to you about AI search.
I checked this with my own talk’s topic. I pulled the US results for “serp analysis” from DataForSEO for five dates in 2026, with the sources Google’s AI Overview cited each time. Between January and August, two to four of the URLs the AI Overview cited also ranked in the organic top 10. In my 22 October pull, none of the eight cited URLs did. It’s one keyword, and the last snapshot is a live pull compared with historical ones, so treat it as an anecdote, not a study. But it’s exactly the kind of thing a rank tracker would never show you.
What I (maybe) should have said at the start
I closed with the caveat I probably should have opened with. Correlation does not equal causation. Just because you see a relationship between, say, entities in titles and rankings doesn’t mean that’s why the content ranks. Every one of these analyses should guide your execution, not dictate it. And data in equals data out: what you put in, in terms of the keywords you analyse, is what you get back. In other words, the analysis does not replace keyword research and content strategy. It makes them sharper.
The recap slide, in what I joked was the longest session ever: you must scale your SERP analysis, build custom SERP reports, and understand the landscape for topics and clusters, not just single keywords. You should use Google’s APIs for entities, sentiment and Knowledge Graph checks, and an LLM to help with labelling. And you could do all sorts of clever things with prediction, provided you have the data, the budget and the will to learn.
What I’d change if I gave this talk tomorrow
The framework stays. The prerequisites stay. Most of the must-haves stay. But four things would change.
- I’d collect on a schedule, not once. In 2022 I treated SERP analysis as a snapshot before writing. SERPs move too fast for that now, and a weekly pull costs pennies through a SERP API. Share of search over time tells you far more than share of search on one day.
- Structured outputs, not free-text prompting. GPT-3 was magic in 2022, and also messy. Constraining the model to your label list is the single biggest reliability upgrade since.
- AI citations would become a must-have. Who Google’s AI Overview and AI Mode cite, and whether you’re one of them, belongs right next to who ranks.
- I’d show a pipeline, not a pile of templates. The templates were the right call for a 2022 audience. Today I’d show how the same steps run as a scheduled script, with an agent on top for the “so what changed, and what do we do?” question.
I’ve written that version up, with code, as a hands-on guide on MLforSEO: 7 ways to automate SERP analysis with AI. It covers SERP APIs and scheduled collection, LLM classification with structured outputs, entity and n-gram gaps, AI Overview and AI Mode citation tracking, share of search over time, clustering keywords by SERP overlap, and scripted versus agentic pipelines.
Slides, templates and code
- The deck: BrightonSEO, October 2022 (PDF).
- The dashboard: the ML-enabled SERP analysis Data Studio template on Data Studio for Marketers is the cleaned-up version of the dashboards in the talk.
- The code: the notebooks for the original methods and the 2026 automation toolkit live in the MLforSEO code hub on GitHub.
- Learn the methods properly: classification, entity extraction and sentiment analysis are all covered hands-on in my Introduction to Machine Learning for SEO course on the MLforSEO Academy.
If you’d rather watch, the 2022 recording is on YouTube.
Want me to give this talk at your event? Book me to speak.
Frequently asked questions
What is SERP analysis?
SERP analysis is studying the search results for your target keywords (who ranks, what type of site they are, which intent they serve, what they talk about and how they phrase it) so you can see what Google rewards before you create content. In 2026 it should also include which sources the AI Overview and AI Mode cite.
How does machine learning help with SERP analysis?
It does at scale what would take days by hand: classifying hundreds of ranking domains by site type and intent, extracting the entities and sentiment across every title and description, and finding the word patterns that dominate ranking titles. You get a structured picture of the SERP you can measure and track, instead of a gut feel from scrolling.
Do I need to code to do this?
No. Everything in the original talk ran in Google Sheets with free templates and a Google Natural Language API key, and the n-gram analysis is a single custom function. Code helps when your keyword lists get big or when you want the analysis to run on a schedule.
Is rank tracking still worth doing?
Yes, but it’s no longer enough on its own. Rankings tell you where your link sits in a list. For queries with an AI Overview, also track which sources the answer cites, because ranking and being cited are increasingly different things.
Written by Lazarina Stoy
Organic growth and AI automation consultant, speaker, and founder of MLforSEO and Data Studio for Marketers. I help marketing teams use AI and automation in ways that are practical, sustainable and scalable.