On this page
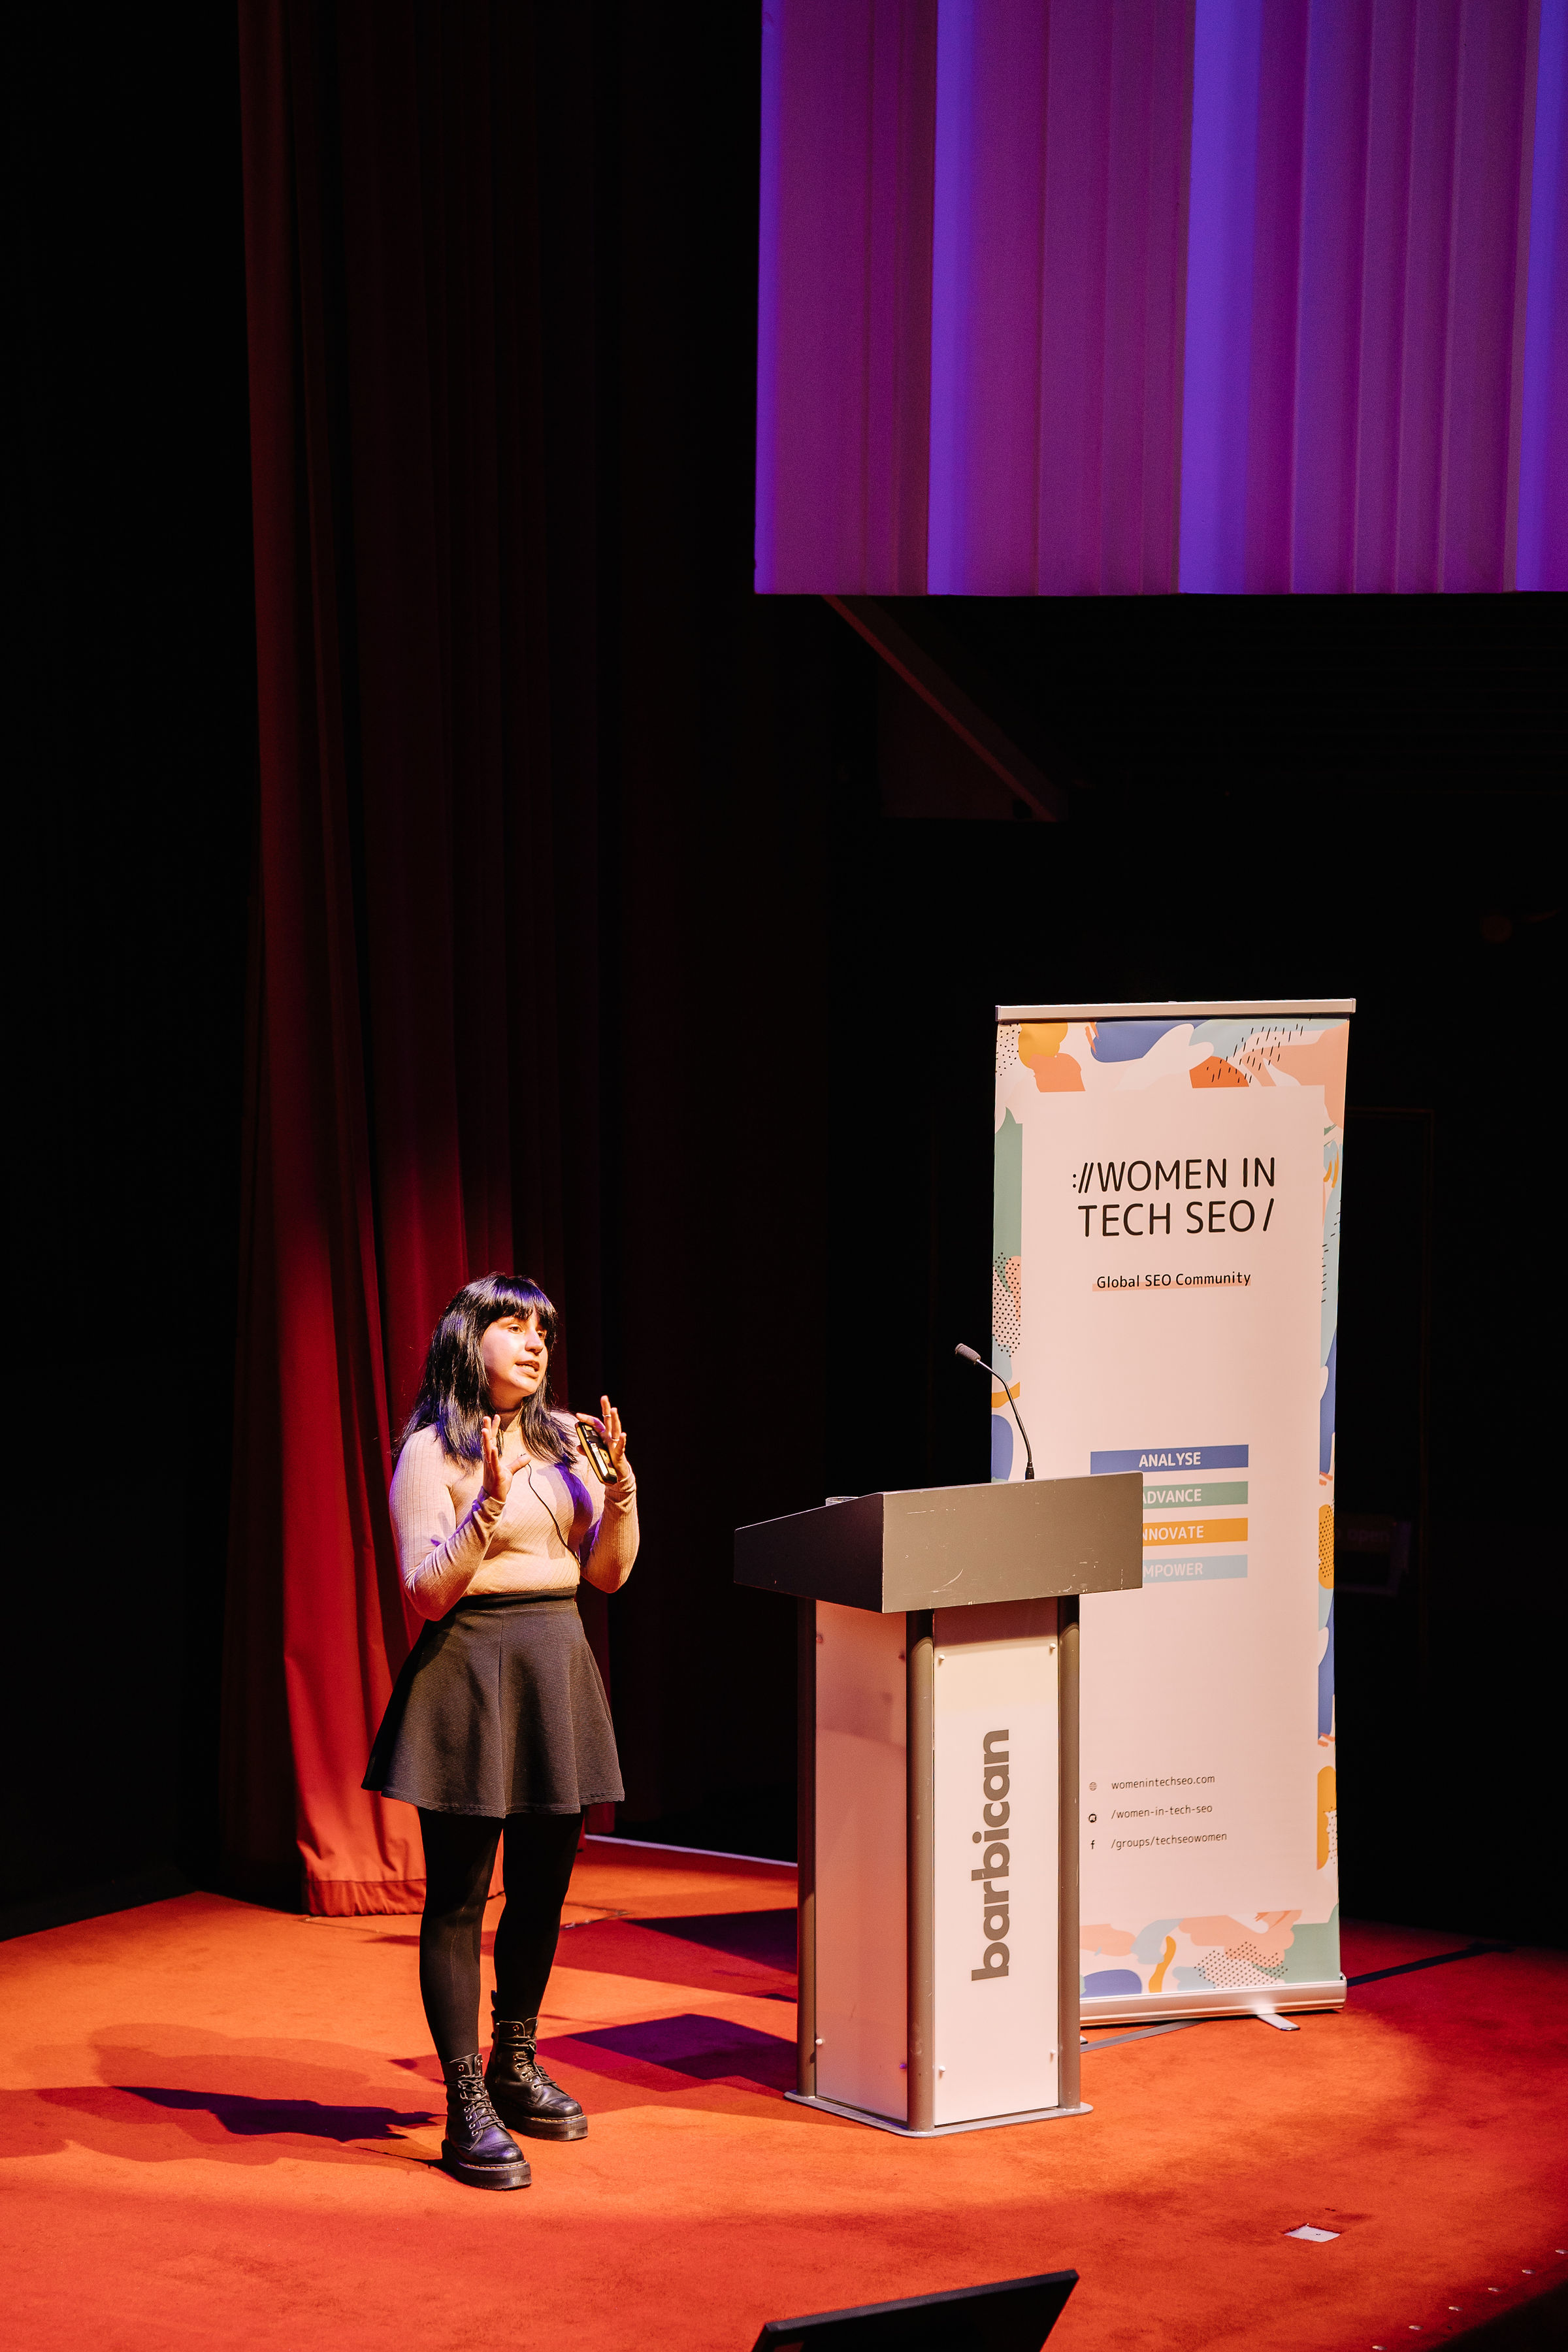
In February 2022 I stood on the Barbican stage at WTSFest and told a room full of SEOs that they didn’t need to become Python developers to start using machine learning. Four years and one generative AI boom later, I still believe that. This guide is that talk, rewritten for October 2026.
About this talk
- Talk: A beginner’s guide to machine learning for SEOs
- Event: WTSFest 2022 (Women in Tech SEO Festival)
- City: London, UK (the Barbican)
- Date: 25 February 2022
- Slides: Download the deck (PDF)
- Series: Part 1 of 2. Part 2 is How to incorporate machine learning in your SEO day-to-day (TechSEO Connect 2024).
A quick thank you before we start: to the Women in Tech SEO community and to Areej AbuAli, whose festival shaped a lot of how I think about teaching technical topics. Back then my job title was Technical SEO Manager, and I opened the talk by listing what I was not: not a Python developer, not a machine learning expert, not a guru. That’s still the spirit of this guide.
This was never meant to be a tactical, copy-this-script talk. It’s the thinking that comes before the script: how to tell whether a task suits machine learning at all, how to find the right approach quickly, and how to keep going when it doesn’t work the first time. That’s also the part that has aged best. The tools changed a lot. The framework barely did.
Here’s what this guide covers:
- Why most SEOs never start (limiting beliefs and a lack of context) and what to do about each.
- My three-part framework for deciding when machine learning fits: task, data and solution characteristics.
- New for 2026: classic ML, purpose-built APIs, embeddings or an LLM? When to use which.
- How to search for a solution, with three worked examples from a typical on-page project.
- How to start practising, plus the habits that kept me going.
I’m also keeping the promises I made on stage. I won’t recite textbook definitions (we can all google things). I won’t tell you every SEO needs to learn Python. And I won’t tell you machine learning is the future of SEO, because in 2026 that sentence has been said so often it has lost all meaning.
What changed since 2022 (and what didn’t)
ChatGPT launched nine months after this talk, in November 2022. Overnight, “machine learning” in most marketing conversations came to mean “a chatbot”. That made it easier to start and, oddly, harder to start well. Plenty of people now stop at a chat window and never learn that there are other, often better, tools for the job. I wrote about where that leads in my piece on whether an AI winter is coming: overpromise, underdeliver, abandon the technology.
So in this rewrite I’ve kept the 2022 framework intact and added what I’d tell that room today:
- Large language models (LLMs) belong in the framework, not on top of it. They are one family of models among several, with clear strengths and clear weaknesses.
- You need even less setup. Google Colab now has an AI agent that can scaffold a notebook from a plain-English description, so “install Anaconda” is no longer step one.
- Several of the no-code apps I recommended are gone. I’ve replaced them with resources that still work.
Why so many SEOs never get started with machine learning
When I gave this talk, Search Engine Journal’s State of SEO survey had just found that 36.3% of SEO professionals spend most of their time on keyword research. Keyword research! Despite all the tools at our disposal, most of our processes were (and frankly still are) fairly manual. And even when a shiny new tool comes along, we struggle to find the time to fit it in.
Time is the obvious excuse. But I’d argue there are two other factors at play, and they’re the ones worth fixing.
1. Limiting beliefs
Do you recognise any of these?
- “You have to be a Python / coding / maths / data science expert to start.”
- “You have to know what every machine learning algorithm does before you start.”
- “You need plenty of free time to learn it all from scratch.”
- “It’s difficult / unattainable / scary / unnecessary.”
These beliefs aren’t unique to SEO. They’re the reasons people across the whole data science field give for never starting, and they’ve been pestering enthusiasts for a long time. Jason Brownlee of Machine Learning Mastery groups the fixes into three situations, and I still think they’re the best advice there is:
- Waiting to get started? Search “machine learning in 10 minutes”, pick a tutorial and follow along. Start small, but do something today.
- Awaiting perfect conditions? The perfect laptop, a clear schedule, the perfect dataset: that timing may never arrive. Build a habit and track your progress.
- Tried and failed? That’s hard, I get it. Cut the scope or change direction, start small again, and stay consistent.

Noticing a pattern? Always start small.
Since 2022 I’ve noticed a new limiting belief join the list, and it runs in the opposite direction: “ChatGPT can do all of this, so why would I learn anything else?” It feels like confidence, but it does the same damage. It stops you from learning which tool fits which job, and you end up blaming “AI” when a general-purpose chatbot gives you different categories every time you ask.
2. A lack of context
The second thing holding people back is context. You’ll often hear advice like:
Just think about things to automate.
Everyone who already knows how to automate things
But to automate something, you need to know what’s possible, especially when you’re short on time. Otherwise you get error after error, wonder why your code isn’t working, get frustrated, try again, fail again, and the whole thing turns into the old joke about never spending six minutes doing something by hand when you can spend six hours failing to automate it.
Context is the cure. So let’s set the right mindset first.
The right mindset for machine learning in SEO

As a beginner, there’s usually no need to reinvent the wheel.
- You don’t need to know a ton of theory.
- You don’t need end-to-end, custom-built, autonomous solutions that run at the click of a button.
- You don’t need to spend a ton of time.
Aim to drive value and have fun with the process. Those are the two things that matter most. If you aim to drive value, you’ll know exactly where a deliverable gets stuck: the step that takes forever, the step you dread. Once you can isolate that step, you can look for a better way to do it, and you’ll save yourself a lot of time. If you’re having fun, you’ll do it more often, and the opportunities start popping up everywhere.
So the perfect starting kit isn’t a degree. It’s knowing three things: which model to use, how to find and implement it quickly, and how to drive value with it. Context becomes everything.
When to search for machine learning: task, data and solution
This is the heart of the talk, and it’s the same framework I still teach today. Whenever you meet a task, look at it from three angles: the characteristics of the task, the data and the solution. (If you want it as a printable, MLforSEO has a when-to-use-machine-learning decision checklist.)
Task characteristics
In the most basic sense, machine learning tasks split into supervised and unsupervised, and those split into four very common groups:
- Supervised machine learning means you have labelled data to validate the results against.
- Regression: making predictions (traffic next quarter, say).
- Classification: sorting things into groups you already have labels for.
- Unsupervised machine learning means you don’t have a way to validate the model’s output.
- Clustering: finding patterns and grouping data points by similarity.
- Dimensionality reduction: simplifying or transforming your data.

Beyond the basics, you’ll find maps of the whole field, like Karen Hao’s brilliant Is this AI? flowchart for MIT Technology Review. Is it looking for patterns in massive amounts of data? Then it’s machine learning. Is it told what to look for? Supervised. Is it learning by trial and error towards a goal? Reinforcement learning. Does it involve deep neural networks? Deep learning, which can be supervised or unsupervised.
The 2026 addition: generative models (the LLMs behind ChatGPT, Gemini and Claude) sit inside this map, not outside it. They are deep learning models built on the transformer architecture, trained on vast amounts of unlabelled text. That matters because it tells you what they inherit: they’re unsupervised at heart, so you can’t take their output as validated, and they’re deep learning, so you can’t easily explain why they said what they said. Keep that in mind for the solution questions below. In part 2 of this series I also cover the other choice that sits under task characteristics: whether to train a model yourself, use a pre-trained one, or fine-tune one.
Data characteristics
Next, what type of data are you working with? This defines the kind of model you’ll search for.
- Numeric: organic clicks or sessions, for a forecast.
- Textual: the copy on your blog pages, if you want to classify them into categories.
- Image-based: your image library, if you want to generate alt text or group images by similarity.
- Time series: anything measured over time, where the order of the data points matters.
Since 2022, more models are multimodal, meaning one model can take text and images (and sometimes audio) together. That’s useful, but don’t let it blur the question. You still need to know what goes in and what you need to come out.
Solution characteristics
Now the solution. How do you know whether machine learning is a good fit? A simple Q&A:
- Is the task mission-critical? Then don’t rely on machine learning. Seriously. As a beginner you’ll mostly use pre-trained models that weren’t built with SEO data in mind, so they will sometimes fail.
- Must the results be consistent every time? Then don’t rely on it either (yeah, really). Unsupervised models in particular can give you different output on each run, even on the same dataset.
- Must the results be easy to understand and explain to a stakeholder? Skip deep learning. How it reaches an answer is very hard to deconstruct for the average Joe like you and me.
- Is it okay that, on average, the output simply outperforms your current method? Faster, cheaper, more scalable? Okay, then. Look at machine learning options.

These four questions are the part of the talk I’m proudest of, because the LLM era proved them right. On consistency: a 2024 study testing several LLMs on the same tasks with “deterministic” settings still found accuracy varying by up to 15% between identical runs. On explainability: LLMs are the deepest of deep learning. If your task fails questions two or three, a chatbot is not the shortcut it looks like.
Assess the bottom line using multiple factors
The takeaway: before you implement anything, assess it using several factors.
- Insights: what will the model actually tell you?
- Complexity: not only to run it, but to interpret the results.
- Scalability: can you repeat it across a portfolio of clients, or on a smaller or bigger dataset?
- Assets: your data’s type, quantity and quality. A model is only as good as the data you give it.
- Accuracy: how well does this model do this task? Published papers on Google Scholar and practitioners’ tutorials usually report it. How much accuracy you need depends on how important the task is.
- Resources: how much help exists online already? With a tight deadline and little experience, a task with few tutorials is a hard place to start.

Put together, these give you the bottom line: is machine learning a good solution for this task, or not? Once you get used to the checklist, it takes minutes. You’ll find some tasks suit it and others don’t, and that’s perfectly okay.
If I gave this talk today, I’d add two factors to the list. Cost per run, because LLM APIs charge per token and an approach that’s cheap on 50 pages can be expensive on 500,000. And footprint, because every model call uses energy. I’ve spent the last year speaking about the sustainability of AI in marketing, and “do I need a large model for this, or will a small one do?” is now a question I ask on every project.
Classic ML, APIs, embeddings or an LLM? When to use which in 2026
This is the section I most wanted to add. In 2022 the main choice was “find a script or a pre-trained model”. In 2026 most SEOs have four broad options, and the framework above tells you which one to reach for.
| Approach | What it is | Reach for it when | Watch out for |
|---|---|---|---|
| Classic ML | Regression, k-means clustering, decision trees and similar, often via scikit-learn in Python | You have numeric or tabular data, need explainable results, or want a forecast | Needs clean data and some setup |
| Purpose-built pre-trained APIs | Models trained for one job: Google Cloud Natural Language (classification, entities, sentiment, moderation), speech-to-text, vision | You need the same answer every time, a confidence score, or structured output at scale | Fixed label sets; costs per call |
| Embeddings + clustering | Turning text into vectors that capture meaning, then grouping or comparing them (sentence-transformers, BERTopic, Gemini or OpenAI embedding models) | Keyword and content clustering, semantic similarity, internal linking, redirect mapping by meaning | You still have to name and sanity-check the clusters |
| LLMs | General-purpose generative models (Gemini, GPT, Claude, open models like Llama) | You need words: drafts, summaries, rewrites, transformations; or quick labels for a custom taxonomy | Inconsistent runs, confident errors, cost and energy at scale |
My rules of thumb, which are really the solution questions in a trench coat:
- If you need the same answer twice, start with an API or classic ML. A purpose-built model returns the same output for the same input, plus a score you can set a threshold on.
- If you need groups, start with embeddings. Then, if you like, ask an LLM to suggest a name for each cluster. That’s a great use of it.
- If you need words, use an LLM, and give it structure. Feed it real data (product specs, reviews, your own content) rather than asking it to invent, and you cut the room it has to make things up.
- If you have labelled examples, use them. Even a few hundred labelled rows change the game: you can train or fine-tune a small classifier, or at least measure how well an LLM is doing.
Two developments since the talk make LLMs more usable for structured SEO work, and I want to be fair to them. First, the major APIs now support structured outputs: you give the model a JSON schema and it always returns valid output in that format. Note what that guarantees, though: the format, not the truth of the values inside it. Second, batch processing got cheap: OpenAI’s Batch API, for example, offers a 50% discount for jobs that can wait up to 24 hours, which suits classification and embedding jobs.
Even so, the research keeps landing where my talks did. A 2024 comparison across several text classification tasks found that smaller fine-tuned models beat zero-shot generative models like ChatGPT and Claude in every case they tested. And when I compared GPT-4 with Google Cloud on nine SEO tasks for Search Engine Land, the purpose-built API won on the precision tasks. (I go through those use cases one by one in part 2.)
I’m not saying “never use an LLM”. I use them every day. What I am saying is: don’t use a blanket model for all your tasks. Use the framework to pick the right one.
How to search for the right machine learning solution
Once a task passes the framework, keep your search specific to the data, the task and the solution. Jason Brownlee has a lovely way of phrasing this as a mission statement. A forecasting project, for instance, becomes: find a model or procedure that makes the best use of historical inputs and outputs to skilfully predict outputs for new, unseen inputs. It sounds dry, but it points you in exactly the right direction.
Let’s put it into context. A typical on-page optimisation project contains several mini-projects. Here are three, run through the framework.
Example 1: Writing meta descriptions
- Input data? Textual: the page content.
- Supervised or unsupervised? Unsupervised. We have no way to validate the results.
- What type of model? Transformational (page content to a summary under about 160 characters) or generative (written from scratch).
- Mission-critical? No.
- Different results okay? Yes.
- Explanation of the process needed? Not really.
- Outperforms current methods? Yes, much faster.

In 2022 my search query was “python script meta descriptions” or “python script text summarisation unsupervised”. In 2026 this is a textbook LLM job: it passes every solution question, and the output is words. If you want to see how the approaches evolved, MLforSEO has a walkthrough that goes from BERT summarisation to LLMs for meta descriptions.
Example 2: Title and H1 optimisation
- Input data? Textual: the page content (and ideally, your search queries).
- Supervised or unsupervised? Unsupervised again.
- What type of model? Transformational (under about 60 characters) or generative.
- Mission-critical? Hm, debatable. This is exactly why the question matters.
- Different results okay? Again, debatable.
- Explanation of the process needed? Kind of.
- Outperforms current methods? Faster, yes. Better, not always.
Some people have done this brilliantly, like the late Hamlet Batista with his deep learning approach to title tag optimisation. But on authoritative or your-money-or-your-life (YMYL) sites, a rewritten title can say something the page doesn’t, and that’s a real risk. My 2026 version: let an LLM draft options, ground them in the queries the page actually gets (MLforSEO has a tutorial on combining fuzzy matching, Search Console data and OpenAI for this), and keep a human on the final call.
Example 3: Image alt text generation
- Input data? Images with missing alt text.
- What type of model? A pre-trained image recognition or captioning model; generative.
- Mission-critical? No.
- Different results okay? Yes.
- Explanation of the process needed? Not really.
- Outperforms current methods? Yes, much faster and scalable.
Back then the query was “image recognition caption generation python script”. Today, multimodal LLMs write genuinely decent alt text from an image. Still check the output, especially for product images and anything with text in it, because a confident wrong description is worse than none for someone using a screen reader. And please, if an intern is still writing your alt text by hand in 2026, free them.
“Surely a script can’t do all that?”
An on-page audit might also involve predicting traffic based on a keyword’s presence in titles, updating internal links, researching keywords with search intent classification, or extracting entities. I know what you’re thinking. Surely one script can’t do all that?
No. One script can’t.
But a few can. Remember the mindset: you don’t need a fully automated, autonomous solution to add value. Incremental improvements compound. Every small step you automate leaves more time for the work that actually advances your career and your client’s revenue: leadership, growth strategy, user research, scalable content systems.
How to start practising machine learning as an SEO
In 2022, step one was installing Anaconda and pip. You can still do that if you want a local setup, but it’s no longer the place to start. Here’s my updated version:
- Open Google Colab. It runs Python in your browser with the main machine learning libraries already installed. Since 2025 it also has a Data Science Agent (in selected countries) that can generate a working notebook from a plain-English description.
- Get your foot through the door with ten minutes of practice a day. One tutorial, one notebook, one small dataset.
- Then get on with your job as usual. When you meet a task that matches the characteristics above, an idea will pop up.
And when it does, work through it in six steps:
- Deconstruct the task into its smallest parts.
- Assess whether machine learning is the right approach, using the framework.
- Gather or prepare your data for the model you’ve chosen.
- Build or test the scripts, libraries and tools you’ve found.
- Assess the results. Scrutinise the output and compare it with another method if you can.
- Document the journey (in public, if possible) and build your deliverable.

Sometimes you’ll find machine learning doesn’t make it into the final deliverable, even though you tested it. Trust me, that still makes your argument stronger. “I tested an automated approach and here’s why the manual one wins for this client” is a far better sentence than “I didn’t look”.
One 2026 caveat on step four. AI coding assistants will happily write a whole script for you, and that’s great, but don’t run code you can’t roughly follow. Ask the assistant to explain each step, then change one thing and see what breaks. That’s how you learn, rather than collecting notebooks you’re scared to touch.
Best-practice tips for getting started
Find a buddy
Practising with someone, or joining a community of like-minded, tech-curious people, can be a game-changer for your mindset. It helps with accountability for your daily (or weekly) practice, and a one-to-one bond built on shared interests is great for ideas, troubleshooting and advice.
Find the right tribe
Jason Brownlee wrote about finding your machine learning tribe, and not just any tribe: the right one for you. I wholeheartedly agree. Most SEOs fall into one of two:
- Business tribes: business people with general interests, and managers trying to deliver a particular project.
- Data tribes: data scientists who want better answers to business questions, and analysts who want to explain data better.
Branch too far outside your tribe (into hardcore research or engineering communities, say) and it can feel discomforting at best and demotivating at worst. Find people who speak your language and share your challenges, and you’ll have a far more relaxed relationship with failing in public.
Set reasonable expectations
It’s easy to believe machine learning can help with every project and scale across your whole client portfolio. The reality is different. No algorithm is perfect, and most weren’t designed to solve SEO problems. So we have to adapt both how we frame the problem and how we interpret the result. In my eyes, machine learning tools are always an ally, as opposed to a replacement. That was true of 2022’s scripts, and it’s just as true of 2026’s chatbots.
Acknowledge your limiting beliefs, then ignore them
Don’t let them keep you from experimenting.
Collaborate and build relationships
Ask for help when you need it. Developers and more experienced SEO builders are usually happy to lend a hand, and the SEO community has always been generous with its code.
Test, test, test
Test scripts, tools and software as they pop up. Work through your backlog of cool things to try. Dissect the scripts you find: what do you like about them, what don’t you like? Note the best practices. After a while, building your own becomes much easier.
Fired up? Where to go next
This talk was conceptual on purpose. Part 2, my TechSEO Connect 2024 talk, is the practical follow-up: nine machine learning projects you can run this week, from text classification and entity extraction to speech-to-text, with a no-code template for most of them.
And if you’d like the structured version, with someone (me) walking you through it, I turned this framework into the Introduction to Machine Learning for SEO course on the MLforSEO Academy. It’s self-paced, beginner-friendly, and takes you from “why use ML at all” through classification, clustering, entity extraction, fuzzy matching and content transformation, with a Colab or Sheets template for each.
A few free resources that are still going strong:
- The MLforSEO resource library: no-code Google Sheets templates, Colab notebooks and Data Studio dashboards for the tasks in this guide.
- My collection of beginner Colab notebooks on GitHub, put together for this talk, including a selection of Britney Muller’s notebooks for SEOs.
- The keyword clustering app by Lee Foot and Charly Wargnier.
- jsLDA, a browser-based topic modelling app from Cornell, which pairs nicely with MLforSEO’s LDA topic modelling tutorial.
And go and follow the people who inspired this talk and taught me so much: Britney Muller, Ruth Everett, Charly Wargnier, Lee Foot, Greg Bernhardt, Andrea Volpini, Michael Van Den Reym, Daniel Heredia, Moshe Ma-yafit and, always, Hamlet Batista.
Want me to give this talk at your event? Book me to speak.
Frequently asked questions
Do I need to learn Python to use machine learning for SEO?
No. Plenty of useful machine learning runs from Google Sheets templates or no-code apps. Python helps once you want to scale or customise, and AI coding assistants have made it far easier to pick up, but it isn’t the entry ticket. Start with the task, not the language.
Is machine learning still worth learning now that we have ChatGPT?
Yes, arguably more than before. ChatGPT is one type of model. Tasks that need consistent, explainable, scored results at scale (classification, entity extraction, clustering, forecasting) are still better served by purpose-built APIs, embeddings or classic machine learning. Knowing the difference is what stops you from getting unreliable results and blaming the technology.
What’s the difference between machine learning and an LLM?
Machine learning is the whole field of models that learn patterns from data. A large language model is one kind of machine learning model: a deep learning model trained on huge amounts of text to predict and generate language. Every LLM is machine learning, but most machine learning isn’t an LLM.
What’s a good first machine learning project for an SEO?
Something small and low-risk with text data you already have: classifying your blog posts into categories, extracting entities from your top pages, or clustering a keyword list. Each takes under an hour with a template, and none is mission-critical if it goes wrong.
How long does it take to get useful results?
Your first useful result can take an afternoon if you start with a template. Getting comfortable enough to choose the right approach for a new problem takes a few months of regular, small practice. Ten minutes a day beats a weekend binge you never repeat.
Written by Lazarina Stoy
Organic growth and AI automation consultant, speaker, and founder of MLforSEO and Data Studio for Marketers. I help marketing teams use AI and automation in ways that are practical, sustainable and scalable.